AAAI/ACM AIES · 2026
Frictionless Validation
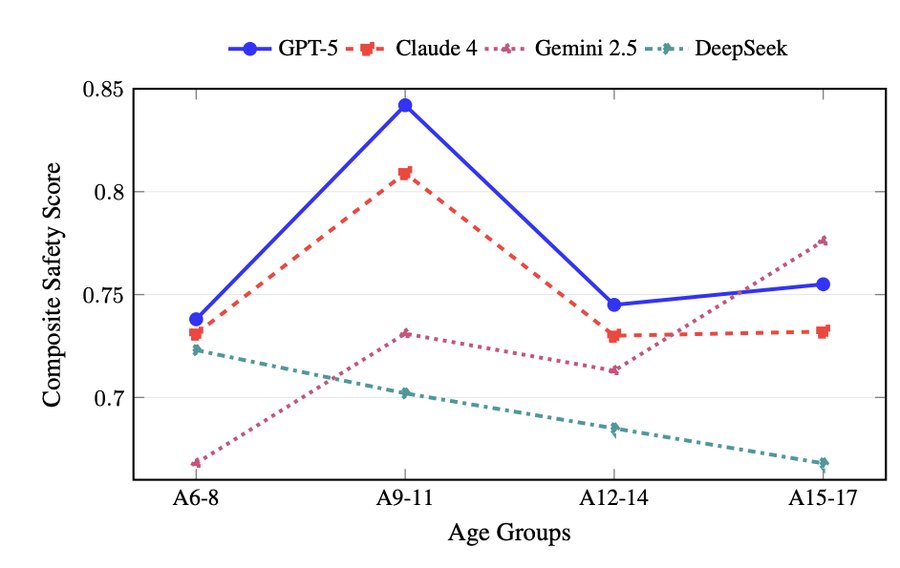
Measures how often frontier models validate young users instead of challenging them, with a new developmental risk index.
I am an AI Research Staff at the Information School at UT Austin, where I work on responsible AI/LLM, reasoning, and interpretable AI in LLMs across domains including science, health, design, and risk management. I led an AI-powered initiative, The-Responsible-AI-Initiative, that probes LLMs for hallucination, bias, and harmful outputs, building its safety benchmarks and the end-to-end ML stack, from data pipelines to model evaluation in PyTorch and scikit-learn. I am also a Research Scientist at SafeKidAI, working on the safety of children’s interactions with LLMs. Since 2023, I have managed the Responsible AI portfolio within UT Austin’s NSF NRT program, coordinating research priorities across disciplines and helping communicate the program’s work to academic, industry, and community audiences. In this role I connect technical AI research with ethics, governance, and real-world use.
I also direct a cross-national explainable AI (XAI) project with 49 scholars from IBM, Google, Microsoft, NVIDIA, MIT, Stanford, and Harvard, among others. Before UT, I was a co-investigator on a Trustworthy AI project funded by the SUNY–IBM AI Research Alliance, designing probabilistic trust frameworks for AI systems.
I have continued to work closely with my advisors, Kush R. Varshney, Jason D’Cruz, Amit Dhurandhar, Ken Fleischmann, Arya Farahi, and Junfeng Jiao. I have authored and led work published in Nature Human Behaviour, Nature Scientific Reports, AAAI/ACM, ICLR, etc.
Measures how often frontier models validate young users instead of challenging them, with a new developmental risk index.
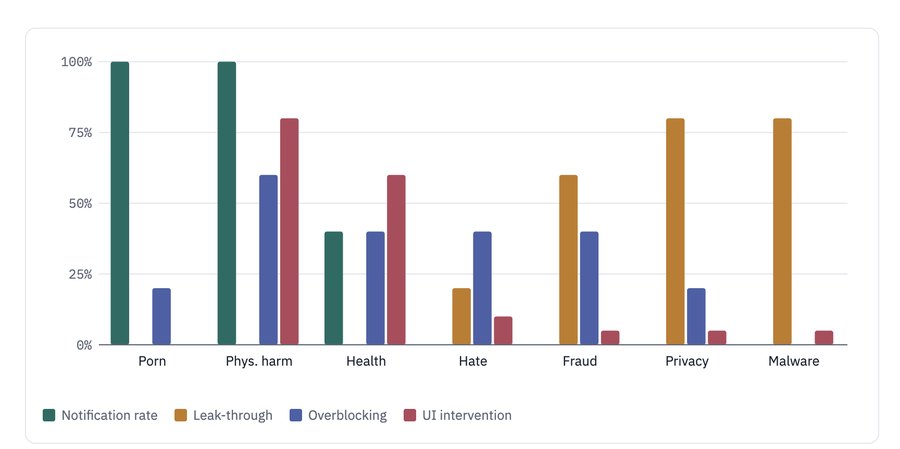
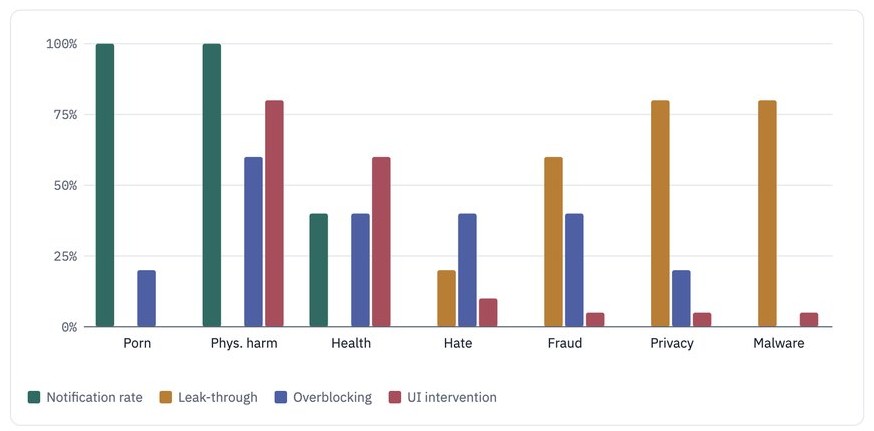
Tests whether ChatGPT’s parental controls actually notify parents, and finds alerts are selective rather than comprehensive.
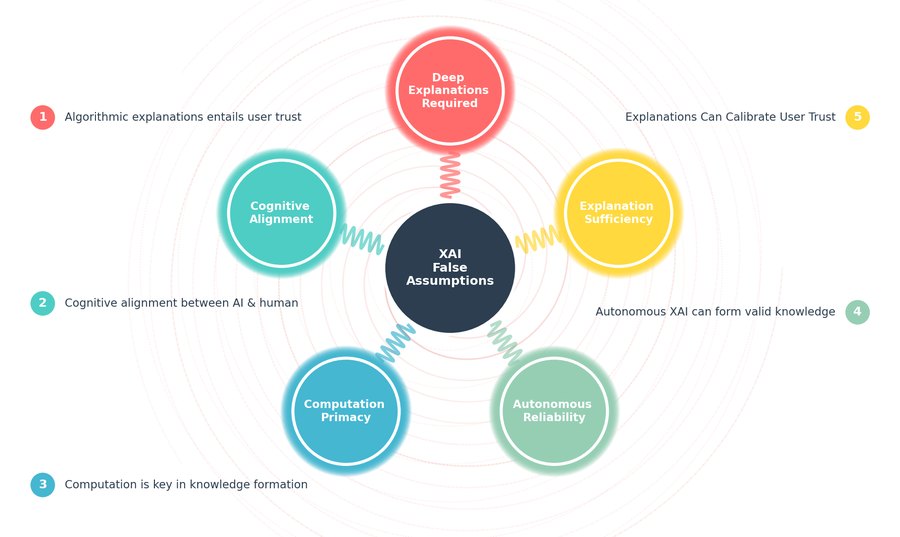
A 49-author diagnosis of why explainable AI falls short for deep networks and LLMs, and a four-part agenda for what comes next.
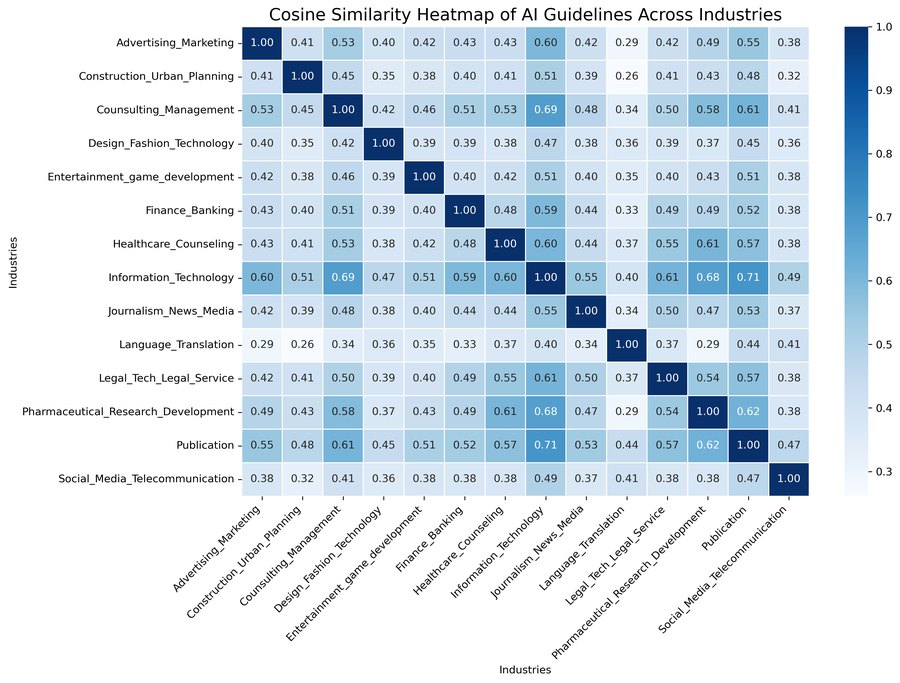
160 corporate AI policies across 14 sectors, clustered into governance themes to show where industries agree and diverge.
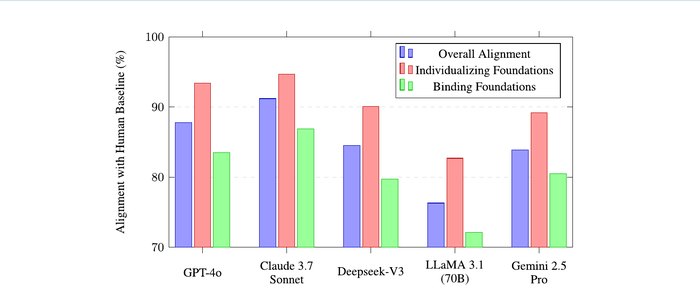
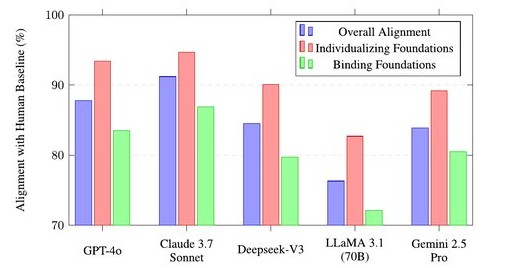
An open benchmark that scores how closely LLMs track human moral judgments across five moral foundations.
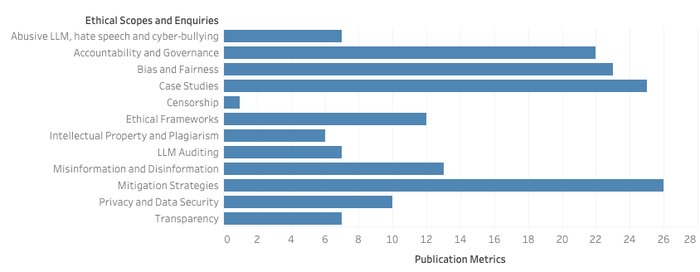
A systematic review separating ethical issues LLMs share with other AI from those unique to LLMs, with mitigations for each.
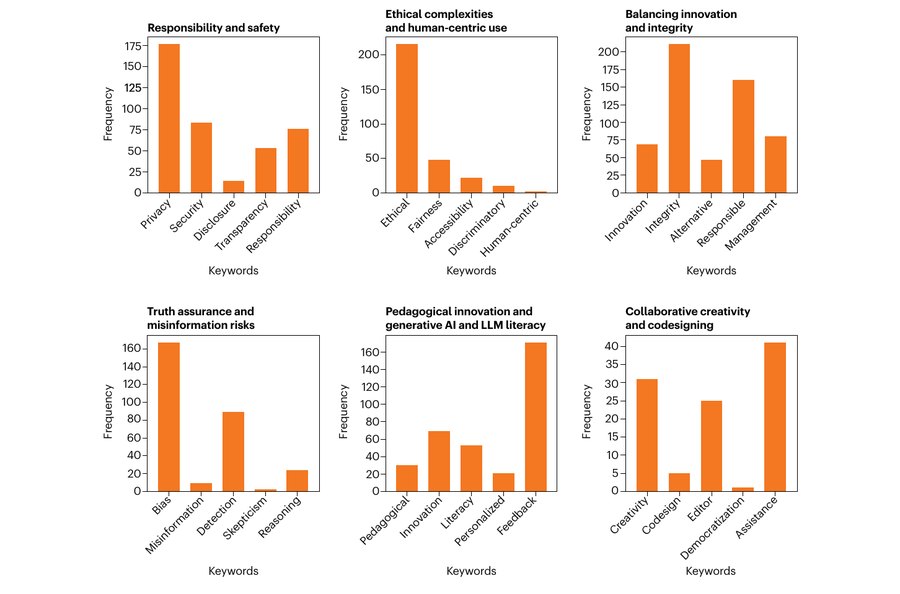
Eighty university guidelines from six continents, analyzed to recommend balanced use of generative AI in education.
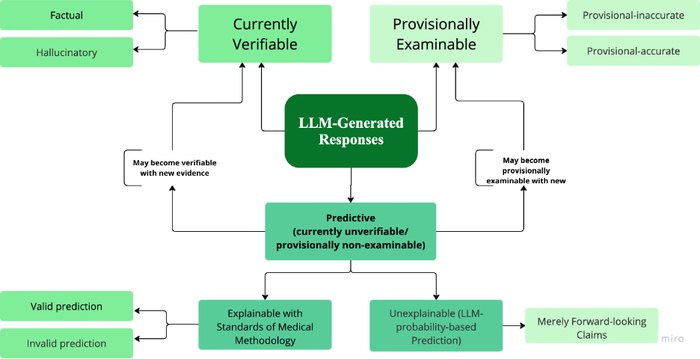
Replaces the true/false view of medical LLM answers with three tiers that account for evolving and predictive knowledge.
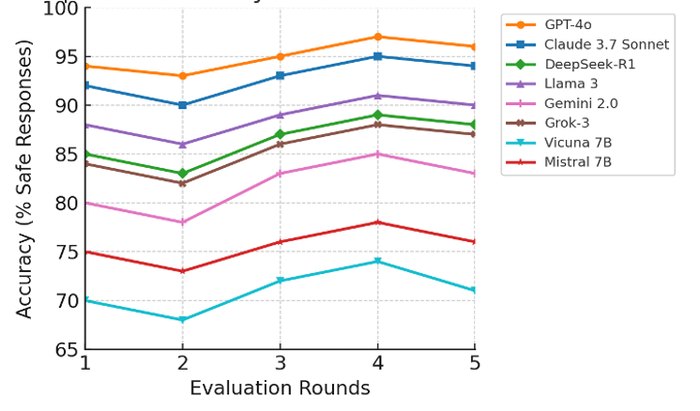
200 adversarial prompts for children (7–12) and teens (13–17), scored on a 0–5 refusal scale across eight leading LLMs.
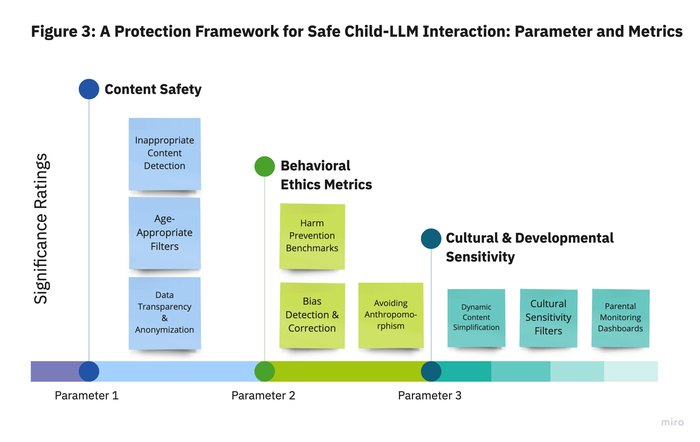
A systematic review of risks children face with LLMs, turned into a protection framework with measurable evaluation targets.
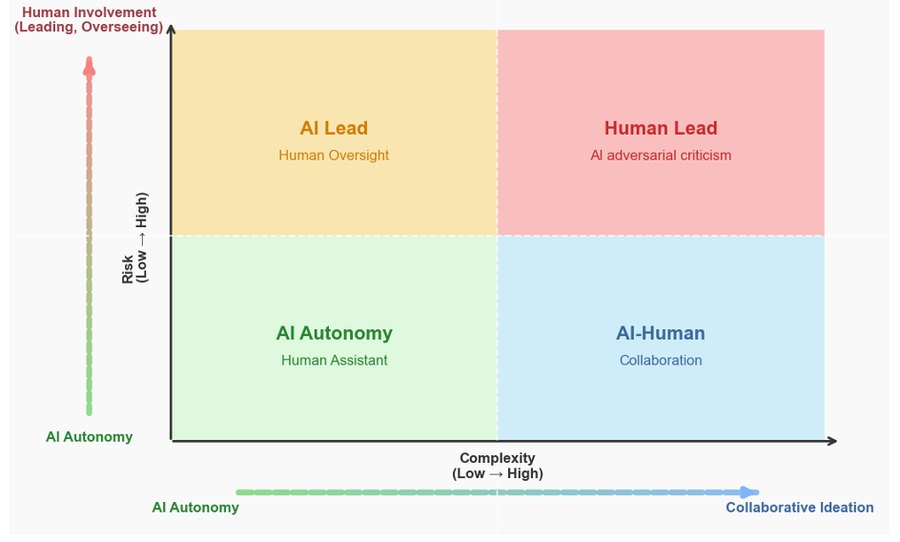
Assigns AI a role (autonomous, collaborative or adversarial) based on a task’s risk and complexity rather than the technology.
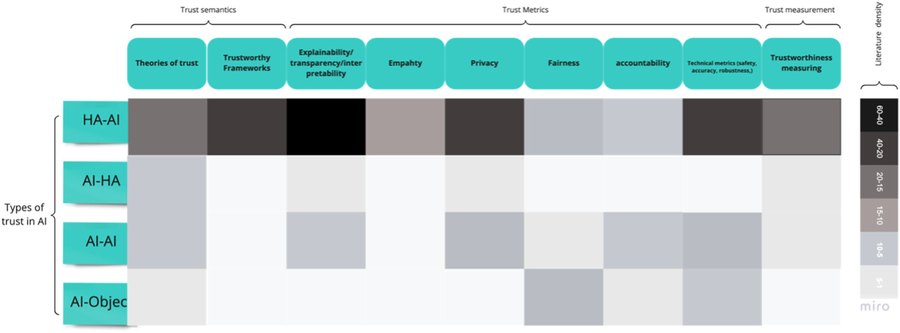
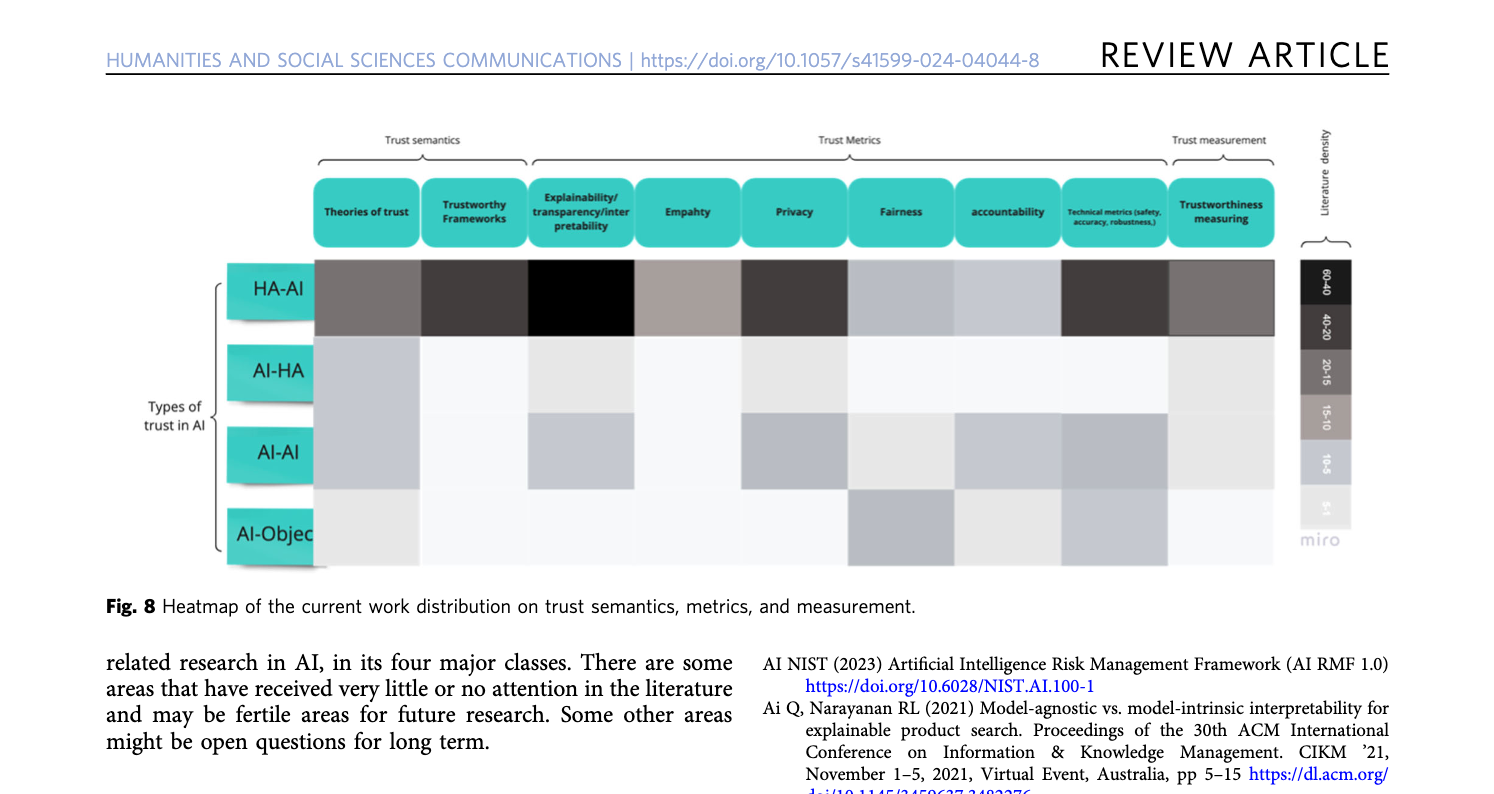
A systematic review of 329 papers on what makes people trust or distrust AI, with a taxonomy of trustworthiness metrics.
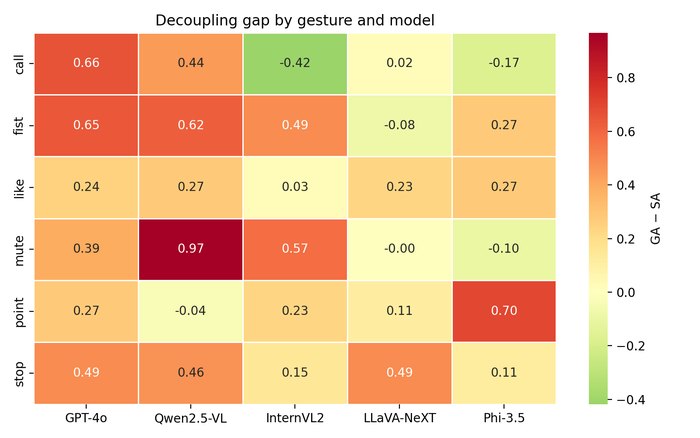
A 4,800-item benchmark showing that VLMs can recognize a hand gesture and still choose the wrong safety action.
A Python SDK that simulates children at different developmental stages to audit chatbots over multi-turn conversations.
@inproceedings{jiao2026frictionless,
  title     = {Frictionless Validation: Exploring {AI} Sycophancy and Developmental Risks},
  author    = {Jiao, Junfeng and Murali, Abhejay and Afroogh, Saleh},
  booktitle = {Proceedings of the AAAI/ACM Conference on AI, Ethics, and Society},
  volume    = {9},
  number    = {2},
  pages     = {1410--1420},
  year      = {2026},
  doi       = {10.1609/aies.v9i2.43234}
}
@inproceedings{ersoz2026parental,
  title     = {Parental Notification Gaps in {ChatGPT-5}: An Empirical Study},
  author    = {Ersoz, Kerem and Afroogh, Saleh and Atkinson, David and Jiao, Junfeng},
  booktitle = {Proceedings of the AAAI/ACM Conference on AI, Ethics, and Society},
  volume    = {9},
  number    = {2},
  pages     = {902--910},
  year      = {2026},
  doi       = {10.1609/aies.v9i2.43193}
}
@article{jiao2025llmethics,
  title     = {{LLM} ethics benchmark: a three-dimensional assessment system for evaluating moral reasoning in large language models},
  author    = {Jiao, Junfeng and Afroogh, Saleh and Murali, Abhejay and Chen, Kevin and Atkinson, David and Dhurandhar, Amit},
  journal   = {Scientific Reports},
  volume    = {15},
  pages     = {34642},
  year      = {2025},
  doi       = {10.1038/s41598-025-18489-7}
}
@article{jiao2025global,
  title     = {The global landscape of academic guidelines for generative {AI} and large language models},
  author    = {Jiao, Junfeng and Afroogh, Saleh and Chen, Kevin and Atkinson, David and Dhurandhar, Amit},
  journal   = {Nature Human Behaviour},
  volume    = {9},
  number    = {4},
  pages     = {638--642},
  year      = {2025},
  doi       = {10.1038/s41562-025-02124-6}
}
@article{afroogh2024trust,
  title     = {Trust in {AI}: progress, challenges, and future directions},
  author    = {Afroogh, Saleh and Akbari, Ali and Malone, Emmie and Kargar, Mohammadali and Alambeigi, Hananeh},
  journal   = {Humanities and Social Sciences Communications},
  volume    = {11},
  number    = {1},
  year      = {2024},
  doi       = {10.1057/s41599-024-04044-8}
}
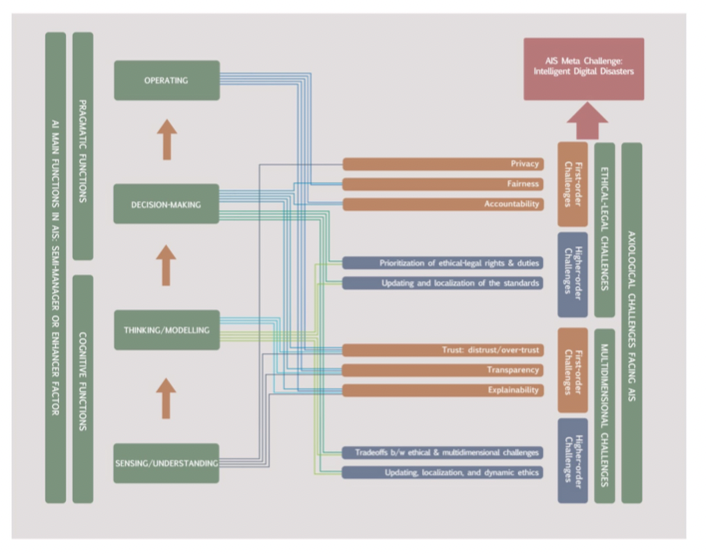
@article{afroogh2024embedded,
  title     = {Embedded ethics for responsible artificial intelligence systems ({EE-RAIS}) in disaster management: a conceptual model and its deployment},
  author    = {Afroogh, Saleh and Mostafavi, Ali and Akbari, Ali and Pouresmaeil, Yasser and Goudarzi, Sajedeh and Hajhosseini, Faegheh and Rasoulkhani, Kambiz},
  journal   = {AI and Ethics},
  volume    = {4},
  number    = {4},
  pages     = {1117--1141},
  year      = {2024},
  doi       = {10.1007/s43681-023-00309-1}
}
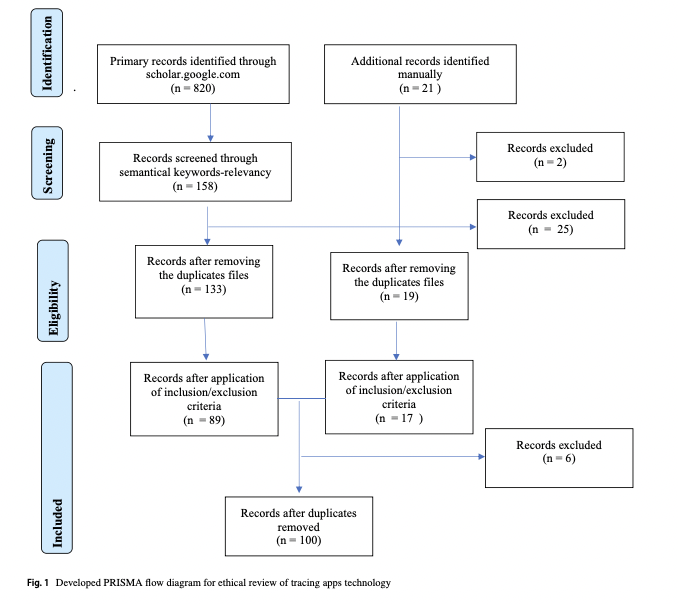
@article{afroogh2022tracing,
  title     = {Tracing app technology: an ethical review in the {COVID-19} era and directions for post-{COVID-19}},
  author    = {Afroogh, Saleh and Esmalian, Amir and Mostafavi, Ali and Akbari, Ali and Rasoulkhani, Kambiz and Esmaeili, Shahriar and Hajiramezanali, Ehsan},
  journal   = {Ethics and Information Technology},
  volume    = {24},
  number    = {3},
  pages     = {30},
  year      = {2022},
  doi       = {10.1007/s10676-022-09659-6}
}
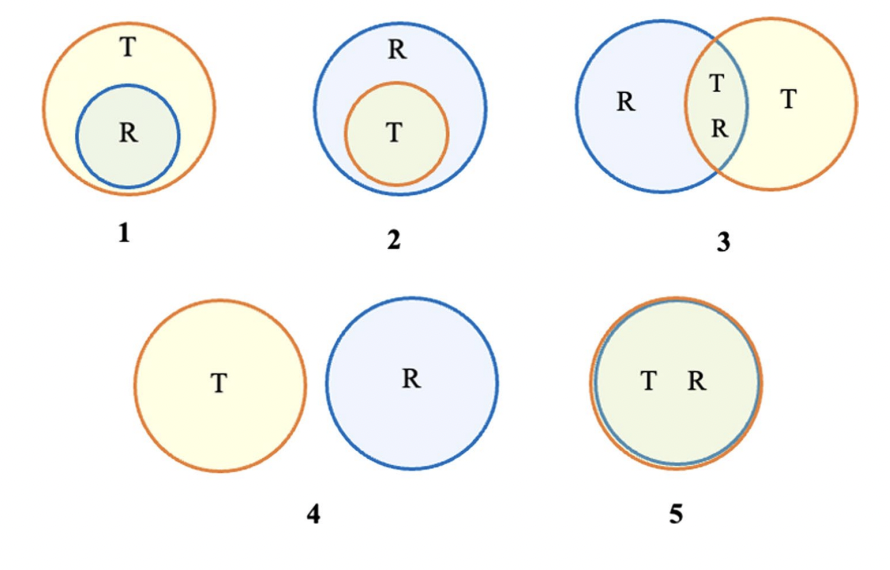
@article{afroogh2023probabilistic,
  title     = {A probabilistic theory of trust concerning artificial intelligence: can intelligent robots trust humans?},
  author    = {Afroogh, Saleh},
  journal   = {AI and Ethics},
  volume    = {3},
  number    = {2},
  pages     = {469--484},
  year      = {2023},
  doi       = {10.1007/s43681-022-00174-4}
}
@article{afroogh2024mirage,
  title     = {The mirage of motivation reason internalism},
  author    = {Afroogh, Saleh},
  journal   = {The Journal of Value Inquiry},
  volume    = {58},
  number    = {1},
  pages     = {111--129},
  year      = {2024},
  doi       = {10.1007/s10790-021-09871-5}
}
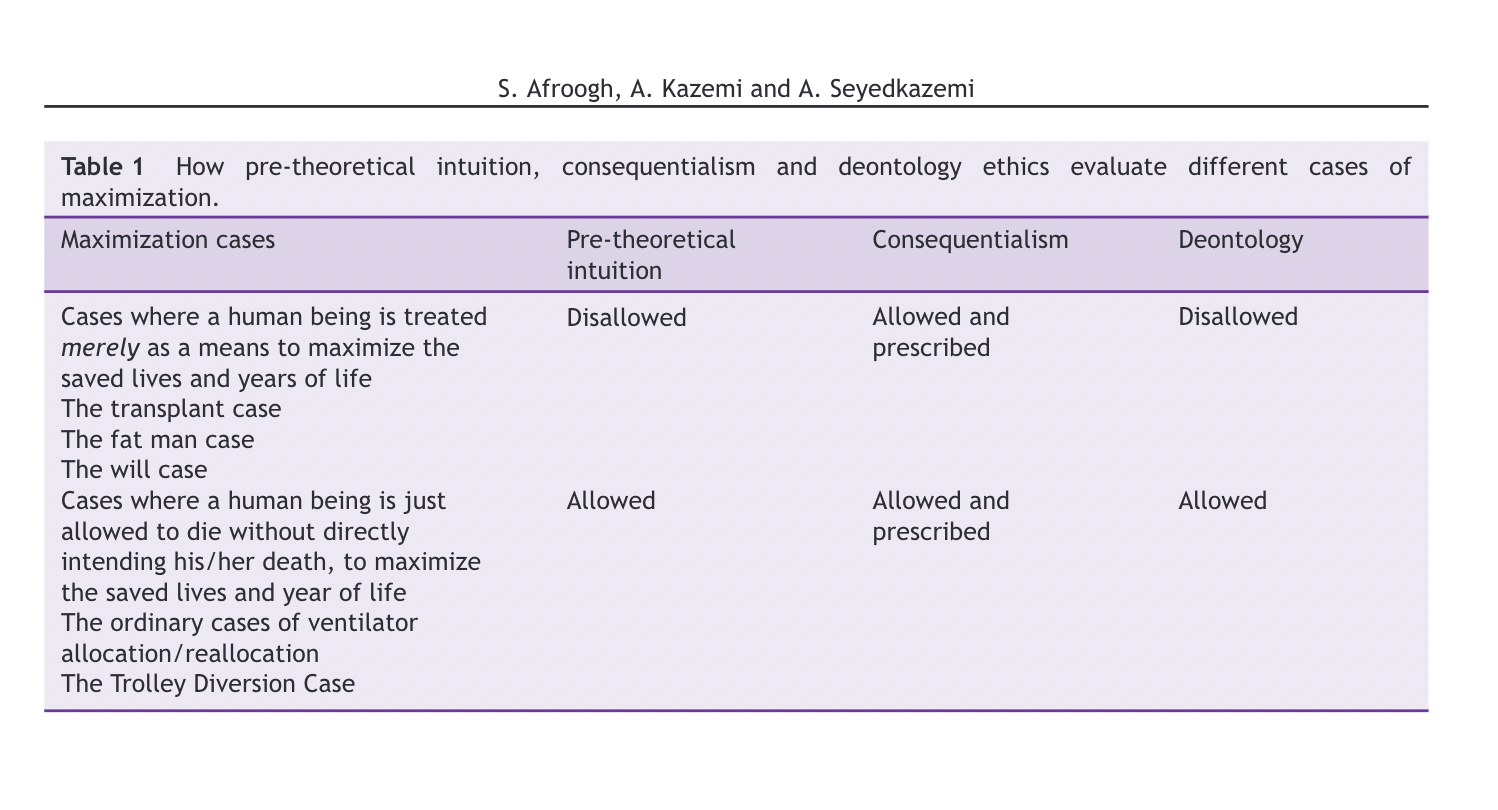
@article{afroogh2021covid,
  title     = {{COVID-19}, scarce resources and priority ethics: why should maximizers be more conservative?},
  author    = {Afroogh, Saleh and Kazemi, A. and Seyedkazemi, A.},
  journal   = {Ethics, Medicine and Public Health},
  volume    = {18},
  pages     = {100698},
  year      = {2021},
  doi       = {10.1016/j.jemep.2021.100698}
}
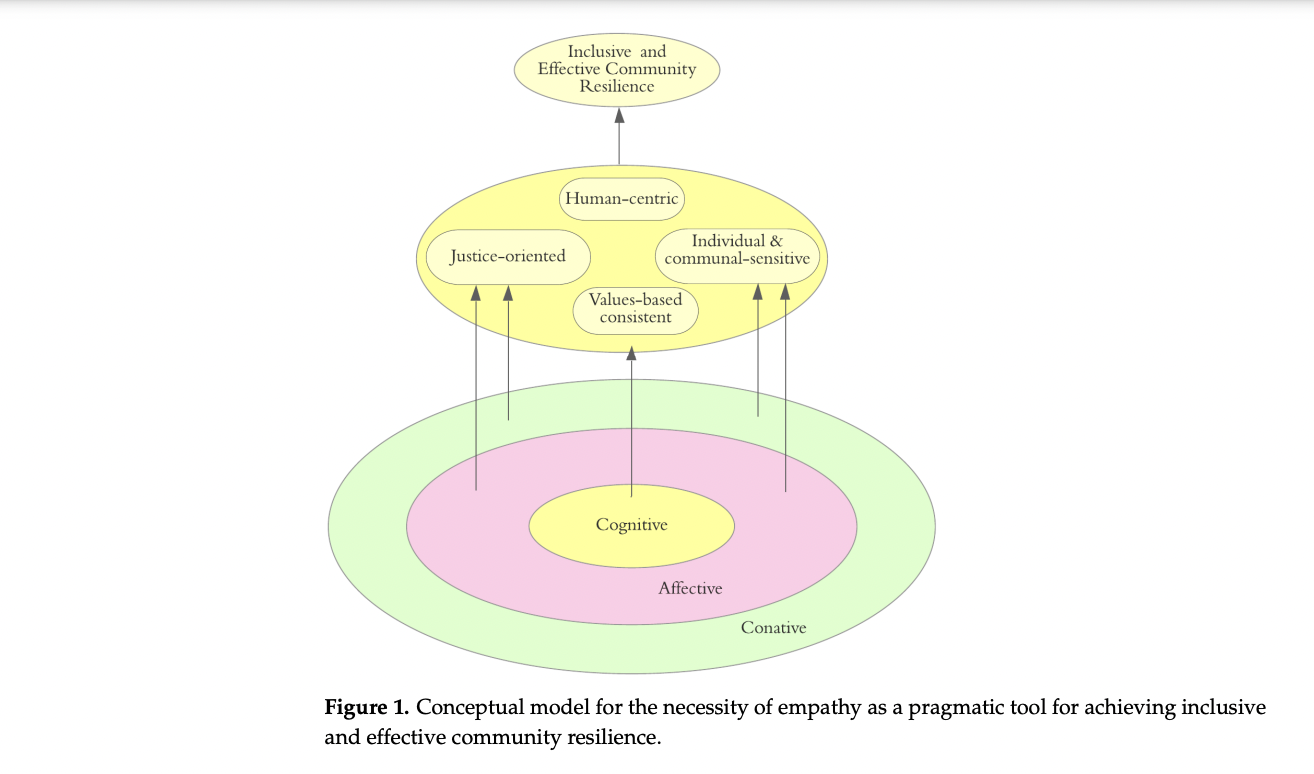
@article{afroogh2021empathic,
  title     = {Empathic design in engineering education and practice: an approach for achieving inclusive and effective community resilience},
  author    = {Afroogh, Saleh and Esmalian, Amir and Donaldson, Jonan Phillip and Mostafavi, Ali},
  journal   = {Sustainability},
  volume    = {13},
  number    = {7},
  pages     = {4060},
  year      = {2021},
  doi       = {10.3390/su13074060}
}
Full list on Google Scholar
Real-world AI incidents involving children and adolescents, coded by sector, harm category, failure mode and severity.
Harvard Dataverse →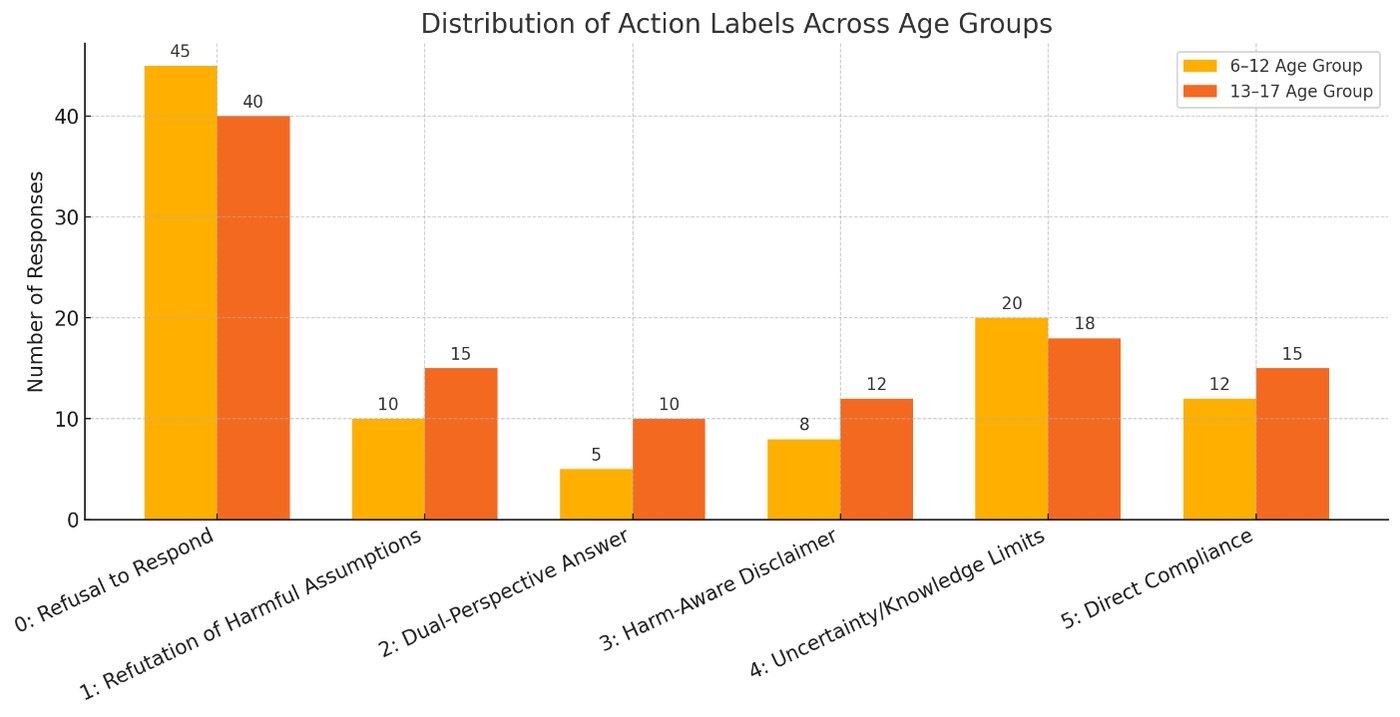
200 child-safety evaluation prompts for two age groups, with harmful-response flags and 0–5 action labels for eight LLMs.
Harvard Dataverse →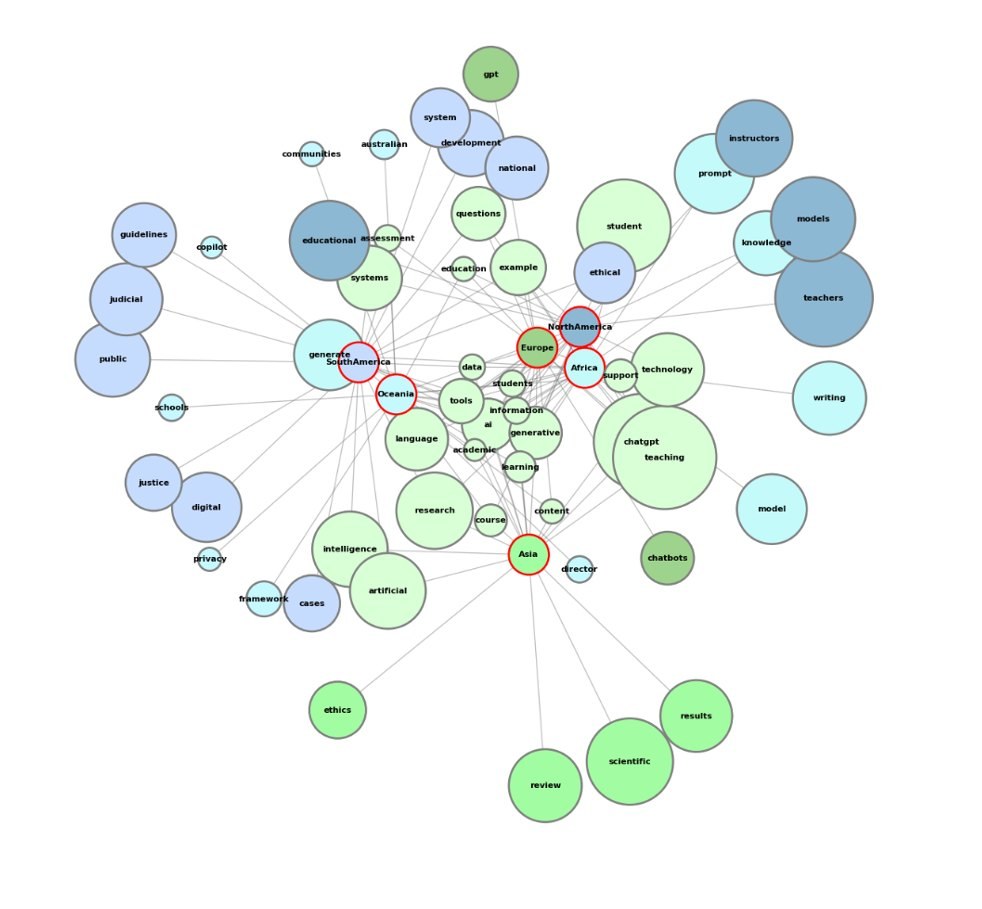
Academic guidelines for generative AI, collected from universities worldwide.
Harvard Dataverse →In my spare time I paint.